Local AI
AI on your own hardware: your data never leaves the building and you do not pay per question. For processes where privacy or volume matters.
- First model liveIn about four weeks
- Runs onYour server or private cloud
- AlwaysData and model are yours
A local model reads a confidential contract on your own server, compares the clauses with your standard and forwards two deviations to legal.
7.2The Supplier's liability is limited to € 50,000 per calendar year, except in cases of intent or wilful recklessness.
8.1The Supplier ensures proper packaging and timely delivery to the agreed address.
9.1Termination must be in writing, observing a notice period of twelve months.
11.1This agreement is governed by German law.
11.2Disputes are submitted exclusively to the competent court in Hamburg.
12.1Amendments to this agreement are valid only if agreed in writing.
Local AI is not for everyone. It is for those with sensitive data or large volumes.
We first work out whether local beats a cloud model. If the cloud is the better choice, we say so.
Data that must not leave the building
Contracts, case files and customer data. Exactly the work where AI delivers the most.
Per-question costs that keep growing
With a cloud model you pay per use. More use means more cost.
Dependent on a supplier
Prices, terms and models change without you having a say.
How we solve it
The solution follows from the problem, not the other way round. These are the building blocks we use most often.
Open-weight models
Models from Qwen, Llama and Mistral, among others, chosen for your task.
On your own hardware
A server at the office, a private cloud or the device itself.
Works with your documents
Searching, summarizing and checking in your own sources.
A model tailored to you
Fine-tuned or shrunk for your task, so it runs fast and lean.
Security and logging
Role-based access and a log of every use.
Maintenance and updates
Testing and rolling out new models when it pays off.
You are not buying a model. You are buying a result.
Up front, we agree what has to improve and how we will measure it. Afterwards, we show you what it delivered.
No cost per question
Measured in cost per month at your volume.Data stays inside
Recorded in the architecture and logging.Faster work on sensitive material
Measured in turnaround time per case.Independent
Measured in what you can swap and run yourself.Outcome agreement
per processMeasure. Build. Own.
After each step, you decide whether to continue.
Measure
The efficiency audit. We map your processes, take a baseline and show you where it pays off, and where it does not.
Build
We build inside your existing systems, in short rounds your team tests itself. The work carries on as normal.
Own
You get everything in your hands. We measure what it delivers against the baseline and adjust. You can leave maintenance with us or run it yourself.
What we build is yours.
No platform you rent and no costs that grow with your usage. You get the software itself, with everything needed to understand and run it.
- Source codein your repository
- Integrations and workflowsdocumented
- Prompts and rulesreadable and editable
- Log of every actionin your own environment
- Maintenancewith us or with you
We don't just write about local AI. We ship it.
Three apps, designed and built by us. The AI model runs on the device itself. No server, no account.

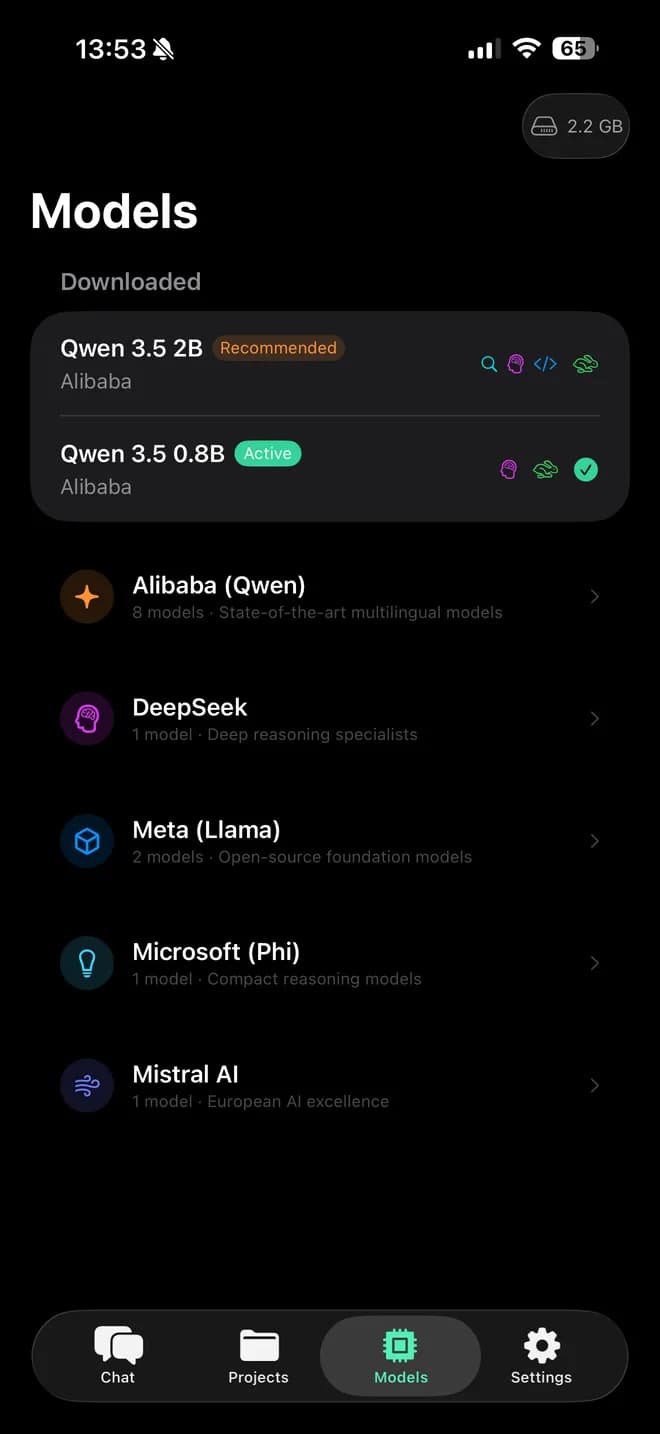
A language model in your pocket. Offline.
Chat with open-weight models from Qwen, Llama, Mistral and others, and ask questions about your own documents. Everything stays on the device.

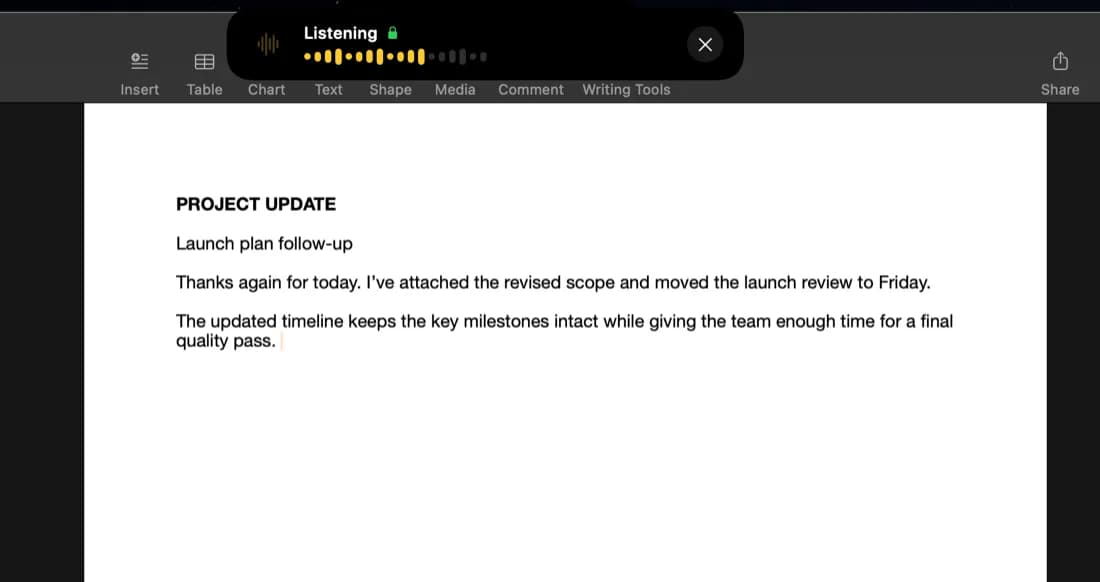
Dictate in any app. Without a network.
Speech recognition runs on the Apple Neural Engine. Dictation never connects to the internet.

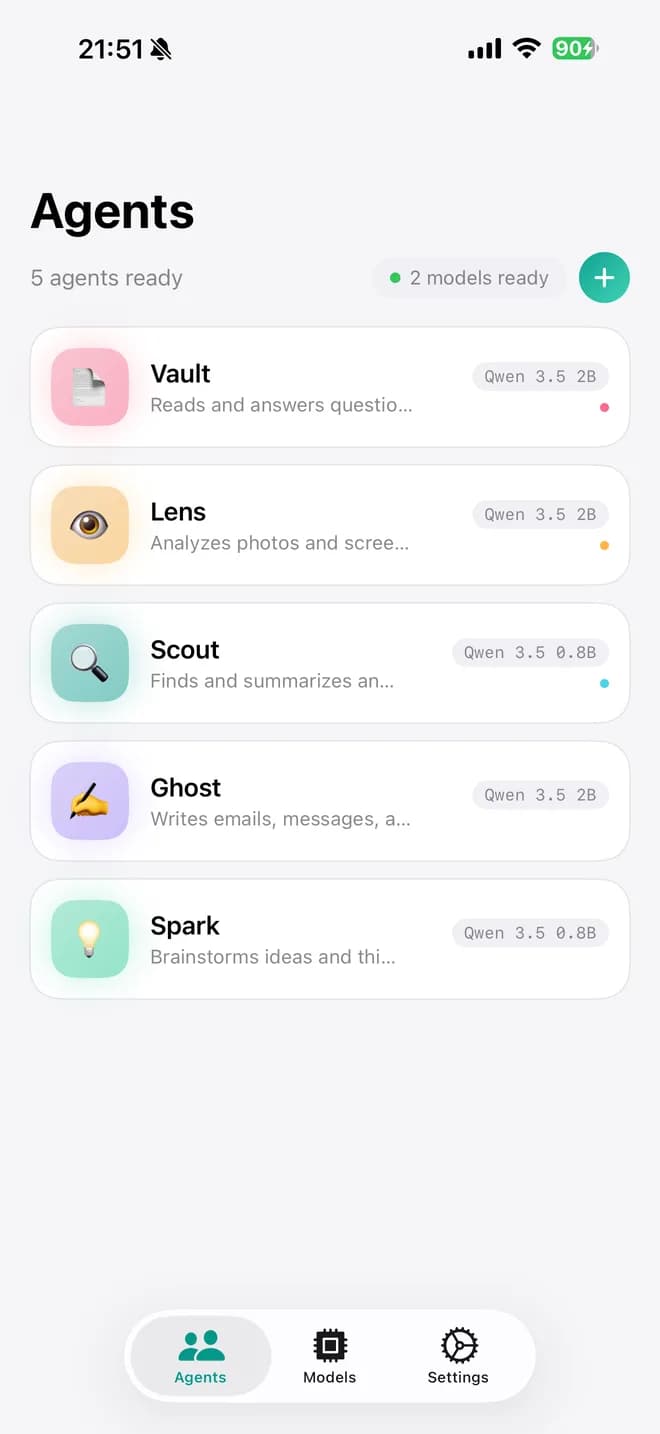
Five AI agents. One iPhone.
Agents that read documents, assess photos and write texts, each with its own local model through Apple MLX. Here Vault answers a question about a lease, and the document never leaves the device.
Choosing models, shrinking them and running them without a cloud. It is the same work we do on your servers.
Local AI for your organizationFrequently asked questions
Not seeing your question? Ask it in the audit.
Local AI is an AI model that runs entirely within your own environment, on your own servers or private cloud, instead of through an external service like ChatGPT or Claude. Your data never leaves your network and you pay no per-question fees. The model is trained on your business data and is your property, giving you full control over privacy, cost and availability.
Yes. A local model can run fully offline, even air-gapped in a network with no internet connection. That's exactly why organizations with sensitive data, such as in healthcare, finance and government, choose it. No request goes to an external server, so there is no risk of data ending up with a cloud vendor or being reused for training.
An owned model becomes cheaper as your volume grows. Cloud APIs charge per token, so your costs rise with every use. A local model has a one-time investment in setup and training plus fixed infrastructure costs, but after that you process unlimited requests with no extra cost per question. At sustained high volume, the investment usually pays back within months. In the free scan we calculate this for your situation.
It depends on the task. For many business use cases a single server with a modern GPU is enough, or even existing hardware for smaller models. We deliberately choose a model size that fits your need, so you don't buy more hardware than necessary. Running in a private cloud is also an option if you don't want to manage your own server room.
Local AI actually makes compliance easier. Because your data never leaves your environment, the biggest GDPR risk of AI disappears: sharing personal data with an external processor. You keep full control over logging, access and decision-making, which supports demonstrable compliance with GDPR, NIS2 and the EU AI Act. We set the system up so you can trace every decision.
Start with the efficiency audit.
We look together at what costs you the most. You get a baseline, an overview of where it pays off and where it does not, and a proposal for the first step.